
Key Takeaways (TL;DR)
No single sales forecasting method can do every job. This guide compares seven methods and explains how to combine them for a more reliable forecast.
- Use stage-weighted forecasting as a simple baseline.
- Add commit calls to inspect important deals more closely.
- Use run-rate and historical data to check whether the forecast is realistic.
- Use cohort models for renewals and expansion.
- Add buyer activity and conversation signals to catch risks before CRM fields change.
- Improve accuracy by cleaning close dates, flagging stale deals for review, and tracking forecast bias.
Sales forecasting techniques are the methods teams use to estimate how much revenue they'll close in a set period, such as next month or next quarter. Here are seven approaches used in B2B sales: stage-weighted pipeline, commit and best case, historical run-rate, renewal cohorts, capacity-based, driver-based regression and machine learning.
Each one has blind spots. Stage weighting can't tell when a deal has gone quiet. Commit calls get inflated when nobody checks them. Run-rate breaks the moment two big deals decide the quarter. In Xactly's 2024 survey of 405 sales and finance professionals in North America, 98% of Finance and Revenue Operations respondents said they struggle when building a forecast.
Many teams handle this by matching each method to the job it does well, then running two or three side by side. The table below compares all seven. The sections after it explain how each one works and where it breaks.
Table of Contents
- The 7 sales forecasting techniques compared
- What is sales forecasting?
- The 7 forecasting methods that actually get used
- Top-down vs bottom-up sales forecasting
- How to choose the right method
- How to create a sales forecast in 4 steps
- Sales forecasting best practices that actually improve accuracy
- A practical 30-day plan
- Sales forecasting example: one quarter, step by step
The 7 sales forecasting techniques compared
Seven methods, seven jobs. Here's the whole set side by side before you decide which two or three to run.
| Method | Best for | Data you need | Where it breaks |
|---|---|---|---|
| Stage-weighted pipeline | Any pipeline, as the explainable baseline | Stage-by-stage historical conversion rates | A silent deal still counts at full weight |
| Commit / best case | A small number of large strategic deals | Manager time to actually inspect | Hard to inspect at high deal volume |
| Historical run-rate | Steady SMB, PLG, self-serve revenue | Four to six quarters of clean history | Any GTM, pricing or segment change |
| Renewal & expansion cohorts | Subscription and consumption revenue | Usage, adoption and retention by segment | CS grading accounts on relationship warmth |
| Capacity-based | Headcount planning and quota setting | Ramp curves, productivity per rep | Ramp times that vary wildly between hires |
| Driver-based (regression) | Finding inputs that help predict revenue | Multi-variable history with clean outcomes | Nobody owns the model after quarter one |
| Machine learning | Early risk detection at deal volume | Enough clean, consistent deal history to test against | Hard to explain without a baseline next to it |
What is sales forecasting?
Sales forecasting is estimating how much revenue your team will close in a set period, such as a month, a quarter or a year. Be clear about what you're forecasting: new bookings, renewals, expansion and total revenue each need different data.
Every forecast draws on three inputs: your open pipeline, your historical patterns (win rates, cycle lengths, seasonality), and leading signals like buyer engagement and product usage.
Every sales forecasting technique below is just a different way of weighting those three inputs. Stage weighting leans on pipeline. Run-rate leans on history. ML leans on signals. Pick based on which input you can actually trust, because a method built on data you don't have won't give you a number you can rely on.
Methods, models, methodologies. People swap these around constantly, and it causes more confusion than it should. Here's what each one actually is:
- A forecasting method or technique is the approach: stage weighting, commit calls, run-rate.
- A forecasting model is that approach built into something that runs, with your numbers in it.
- A forecasting methodology is the boring part nobody writes down: who updates what, how often, and what qualifies a deal for commit.
Most teams have a method. Fewer have a model. Almost nobody bothers with the methodology, which is why the same argument keeps coming up on the same call every week.
Forecasts, targets and predictions. A forecast is your best estimate of the sales you'll likely close in a period. A target is the goal you're aiming for, and it can be higher or lower than the forecast. A prediction is any estimate of an outcome. It can be about one deal, a segment or the whole quarter. Predictions feed the forecast, but the forecast is the number the business plans around.
The 7 forecasting methods that actually get used
A single forecasting model rarely survives contact with a real quarter. Mature teams run two or three at once, compare the outputs, argue about the gaps, and land on a number that's both grounded and defensible.
Here's how each one works in practice, and exactly where each one falls apart.
1. Stage-weighted pipeline forecasting (the opportunity stage method)
Everyone starts here. Assign each pipeline stage a win probability from your historical conversion rates. Multiply. Sum.
The math, with real numbers:
A $100K deal in Proposal at 60% counts as $60K. A $50K deal in Discovery at 20% counts as $10K. A $200K deal in Negotiation at 80% counts as $160K.
Weighted forecast: $230K. Finance can audit it in five minutes. Keep that property. It's rarer than you think.
The failure mode: a $200K deal sits at 80% while the champion goes silent for three weeks. Nobody updates the field. The model keeps counting $160K.
Stage weighting reads fields. It cannot read a champion who stopped replying. So treat it as your baseline, run it every week, and pair it with something that watches deal behavior.
A close cousin is length-of-sales-cycle forecasting. Instead of the stage, it looks at how long a deal has been open compared with your average cycle. A deal that's 60 days into a 90-day cycle gets more weight than one that's 10 days in.
2. Commit / best case forecasting (deal-by-deal judgment)
The method every enterprise team swears by. Reps and managers sort deals into buckets using judgment about champions, politics, and all the things a CRM field will never hold.
Unpopular opinion: with twelve strategic deals and a manager who genuinely inspects them, this beats every model on this list.
Now try it on 400 opportunities. Inspection becomes impossible, and "commit" slowly turns into "the rep really wants this one."
What the forecast categories mean
| Category | Definition | Illustrative weight |
|---|---|---|
| Pipeline | Every open deal with a close date in the period | 10% |
| Best case | Deals that land if things break your way. Upside, not plan. | 50% |
| Commit | Deals the rep and manager put their name on | 90% |
| Closed won | Deals already booked. | 100% |
| Omitted | Deals left out of the forecast. They stay open in the CRM but aren't counted. | Excluded |
The weighted pipeline formula
Weighted forecast =
  Closed won
+ (Commit × 0.90)
+ (Best case × 0.50)
+ (Remaining pipeline × 0.10)
Each deal sits in exactly one category, so nothing is counted twice. "Remaining pipeline" means open deals that aren't already in commit or best case. These weights are for illustration only, so use your own conversion rates.
Say a team hits the last month of the quarter holding:
- Closed won: $1,200,000
- Commit: $800,000 → $720,000
- Best case: $600,000 → $300,000
- Remaining pipeline: $2,400,000 → $240,000
Weighted forecast: $2,460,000.
Here's the bit that usually gets left out. Those weights are not universal. They're your own historical conversion rates by bucket, and they need recalculating every couple of quarters.
Go back through your last four quarters. For each one, take the deals that sat in commit at the start of the final month and add up their value. Then add up how much of that same group actually closed. Divide what closed by the starting value. If $1M sat in commit and $700K of it closed, your commit conversion is 70%, so your commit weight is 0.70. Sticking with 0.90 because some blog said so is how a forecast stays confidently wrong for a year.
What qualifies a deal for commit
Write these down. Undocumented commit criteria are the reason forecast calls turn into arguments about gut feel.
- Economic buyer identified and personally engaged in the last 14 days
- Written confirmation of budget, or paper in legal
- A mutual close plan with dates the buyer has agreed to
- Every open technical and security requirement resolved
- Close date hasn't moved in the last 30 days
Miss one and it drops to best case. Miss two and it's pipeline. And no exceptions in month three, which is of course exactly when everyone starts asking for one.
How to run the forecast call
Most forecast calls are an argument about which deal belongs in which bucket.
Keep the argument. The argument IS the forecasting. A call where everyone nods along produces a number nobody actually believes.
What makes that argument productive rather than exhausting:
- Only inspect movement. Deals that changed bucket, date or amount. Everything else gets skipped, which on its own tends to halve the meeting.
- Ask for evidence, not confidence. "What did the buyer do this week?" beats "how do you feel about this one?"
- Log every bucket change with a reason. Two months from now you'll want to know which manager keeps moving deals into commit too early, and the log is the only place that answer exists.
- Time-box to 60 minutes. If your commit list needs longer than that, your commit criteria are too loose.
Where it breaks
Judgment doesn't scale, and it stops being honest the moment quota pressure shows up. There's no audit trail either, so when the quarter misses nobody can go back and work out why. Pair commit calls with something that watches how deals are actually behaving, separately from what the rep believes.
3. Historical run-rate forecasting (time series and trend extrapolation)
Steady revenue? SMB motion, PLG, self-serve? Take past sales by month or quarter, layer in trend and seasonality, project forward. Done.
Every assumption in this model boils down to one sentence: the future will look like the past. GTM pivot, pricing change, a young startup still finding its buyer, one whale deal in an otherwise steady book. Any of those kills the assumption, and the model with it.
Run it anyway. Here's why.
When your bottom-up forecast says $2.1M and your run-rate says $1.4M, one of those numbers is lying to you. Spend a meeting finding out which one. You'll learn more in that hour than in a month of pipeline reviews.
The run-rate math, with real numbers
Simple moving average. Last three months of closed revenue, averaged.
$420K, $455K, $480K → $451.7K baseline.
It's simple on purpose. It lags a real trend by roughly half your window, but it smooths out noise.
Weighted moving average. Same months, recent ones count more.
($420K × 0.2) + ($455K × 0.3) + ($480K × 0.5) = $460.5K
Add trend and seasonality. Using illustrative assumptions of 6% month-over-month growth and a Q4 seasonal index of 1.15:
$460.5K × 1.06 × 1.15 = $561.3K
The naive method. Next month equals last month. $480K. Sounds useless, isn't. Run it as your control: if your sophisticated model can't beat "same as last month" across six quarters of backtesting, it isn't adding value yet.
4. Renewal and expansion cohort forecasting
Selling subscriptions? Your renewal number deserves the same rigor as net-new. Take your renewal cohorts, apply realistic retention and expansion rates by segment, model what comes back this quarter.
"So where does this one go wrong?"
Feelings. Specifically, Customer Success grading accounts on relationship warmth.
You've watched this movie. Every account shows green. Then the churn email lands, and everyone discovers "green" meant the CSM liked them. Meanwhile usage had been sliding for two months and login counts told the whole story to anyone who looked.
Wire your renewal forecast to usage and adoption data. Sentiment makes a terrible input.
5. Capacity-based forecasting
The question this answers: how much can this team physically produce? Rep count, productivity per rep, ramp curves, pipeline creation rates, conversion rates. Project the output.
Really, this is your planning tool. Can the team hit $12M next year with current headcount? How many AEs need to start in Q1 to protect the Q3 number? Capacity math answers questions no pipeline model can touch.
The weak spot: ramp chaos. If your last four AE hires ramped in 3, 5, 9, and 14 months, your productivity-per-rep assumption is fiction, and everything downstream of it inherits the fiction.
6. Driver-based forecasting (regression or multivariable analysis)
Every method so far assumes something drives revenue: stages, judgment, history, headcount. Regression measures it instead. It tests inputs like pipeline quality, product usage, engagement and marketing activity against past outcomes to find the ones that help predict revenue. It shows relationships, not causes: a factor that predicts well isn't necessarily what makes deals close.
Then reality arrives. The model gets built once, impresses the exec team in one QBR, and sits untouched while the business changes underneath it. Three quarters later someone notices it's been wrong the whole time. A regression model needs an owner who updates it as the business changes.
7. Machine learning forecasting
Machine learning models learn from past deals to estimate how likely each open deal is to close. They can use pipeline data, deal history, conversation signals and usage patterns. Some combine several models into one, which is called an ensemble, but not all do.
With enough clean history, machine learning can spot patterns that are hard for people to track across many deals. How much data you need depends on the model, your sales cycle and how consistent your past deals are, so test it against past quarters before relying on it.
It can still pick up bias. If reps log optimistic stages or close dates, the model learns from those too.
Don't let it stand alone. A probability with no explanation is hard to defend in front of a board. Keep an explainable baseline and use machine learning as an early-warning layer on top.
Top-down vs bottom-up sales forecasting
Top-down (the breakdown approach): start from the market and work down. Estimate demand in your segments, then the share you can realistically win based on your pipeline, team capacity and past win rates. For example, if 400 target accounts are expected to buy this year at about $60K each, that's $24M of demand. If you've historically won about 15% of deals like these, your top-down forecast is about $3.6M.
This is different from allocating a target. Splitting a $12M goal 60/40 between enterprise and mid-market shows where the target goes, not what the market will actually buy.
Bottom-up (the buildup approach): start with individual deals or reps and add them up. Eight reps each expecting about $425K this year gives $3.4M. It's good for accountability, but it can be padded or sandbagged, and it ignores what the market can actually absorb.
Build both and compare. If top-down says about $3.6M and bottom-up says $3.4M, the two views roughly agree. If bottom-up says $2.2M, either the demand assumptions are too optimistic or the pipeline is too thin, and it's better to find that out early.
How to choose the right method
No single method works for every team. Even teams that forecast well run two or three and compare them. A simple way to pick:
- Enterprise teams with a few large deals: commit calls with real deal inspection, plus a driver-based or machine learning model to flag risk.
- High-volume SMB, PLG or self-serve teams: stage-weighted plus run-rate. Commit calls only matter for the occasional big deal.
- Forecasting several quarters ahead: capacity and cohort models.
- When Finance needs to see the math: stage-weighted and cohorts as the main number, with AI signals as an early warning rather than the forecast itself.
A setup that works for many teams:
- Stage-weighted as the baseline anyone can check
- Commit calls so sales owns the number
- Cohort models for renewals
- A signal layer, such as ForecastIQ, that flags risk before CRM fields change
How to create a sales forecast in 4 steps
- Decide what you're forecasting and for when. For example, new bookings for next quarter. Renewals and expansion need their own forecast.
- Clean the pipeline. Fix close dates that keep moving, flag deals with no recent buyer activity for review, and make sure every deal has a stage and an amount. Set the inactivity limit to fit your sales cycle: two quiet weeks is a warning sign in a 30-day cycle but normal in a nine-month one.
- Pick a baseline method and a check. Stage-weighted works as the baseline for most teams. Run-rate from the last four quarters makes a good check.
- Compare, adjust and review weekly. If the two numbers are far apart, dig into the deals driving the gap. Then review every week and note why deals moved.
Sales forecasting best practices that actually improve accuracy
Everyone reaches for a better model. Accuracy almost always improves for less interesting reasons.
Clean the close dates first. Run a report on deals whose close date has moved three or more times. Those are usually the deals that throw the forecast off. A date that keeps moving isn't really a forecasting problem; it usually points to a qualification problem.
Review stale deals on a schedule. Flag deals that have gone quiet for longer than is normal for your sales cycle. The rep either shows recent buyer activity or the deal moves to omitted. Flagging instead of deleting keeps the history, and asking for evidence is the whole point.
Track bias, not just accuracy. This is the one most teams skip and the one that pays fastest. Accuracy tells you that you missed. Bias tells you that you miss high every single quarter, which is a fixable process problem rather than a modelling one. Calculate it as (forecast − actual) ÷ actual, averaged across six quarters. Consistently positive means your commit weight is too generous.
Segment accuracy instead of averaging it. One blended number tells you nothing. Break it out by segment, by rep, by deal size band. The usual finding: enterprise is fine and one velocity segment is dragging the whole number down. You can't fix that until you can see it.
Backtest before you trust. Any new model runs against four to six closed quarters before it touches a board deck. If it wouldn't have called those quarters, it won't call this one.
What to actually measure
There's no universal benchmark for these. Use your own last four to six quarters as the baseline, then set targets that improve on it.
| Metric | What it tells you | How to set your target |
|---|---|---|
| Forecast accuracy | How close the final number landed | Check how far your forecast at fixed points in the quarter (for example week 3 and week 8) landed from the final result, then aim to narrow that gap |
| Forecast bias | Which direction you always miss in | Average (forecast − actual) ÷ actual over recent quarters, and aim to bring it closer to zero |
| Commit conversion | Share of commit that closes. This is your commit weight. | Use your own past rate as the baseline. It's also your commit weight |
| Slipped deal rate | Deals pushed to next period | Track the share of commit pushed to the next period each quarter, and aim to reduce it |
| Week-over-week variance | How much the number moves | Watch how much the number moves each week; it should settle as the quarter goes on |
Then bring in buyer signals. Silence, engagement patterns, usage activation. Tools like ForecastIQ surface the early signals humans miss or avoid updating in Salesforce.
A practical 30-day plan
If you've been asked to improve forecasting this quarter, this plan fits in a month. You can also download the free 30-day forecasting plan spreadsheet and adapt it to your team.
- Week 1: Choose your two or three methods and give each one an owner.
- Week 2: Clean the CRM. Fix close dates, flag stale deals for review and fill in missing stage history.
- Week 3: Build a baseline model and test it against the last four to six quarters.
- Week 4: Start a weekly forecast review. Log every change and inspect the deals that moved.
Once that rhythm is in place, add signal-based forecasting, such as ForecastIQ, on top. It doesn't change your model. It just flags risk earlier.
Sales forecasting example: one quarter, step by step
This example is illustrative. A team wants its Q4 forecast for new bookings. Each percentage is the team's historical rate for a deal in that stage closing within Q4.
Stage-weighted forecast
- Already closed this quarter: $350K
- Discovery: $600K × 10% = $60K
- Proposal: $500K × 40% = $200K
- Negotiation: $400K × 70% = $280K
Forecast: $890K
Run-rate check: the last three quarters closed $820K, $860K and $900K, which averages $860K. Q4 is usually about 10% stronger for this team, so the run-rate estimate is about $946K.
The two numbers are $56K apart, about 6%. A small gap doesn't prove the forecast is right. It just means the two methods aren't pulling in different directions. The team still reviews the Negotiation deals first, because they carry the most weight.
In practice: VAST Data kept an explainable pipeline forecast and added deal signals such as stalled champions, rep inaction and slipping close dates, so managers could step in earlier. Read the VAST Data story.
Every capability walked through one by one, with screenshots from real calls.
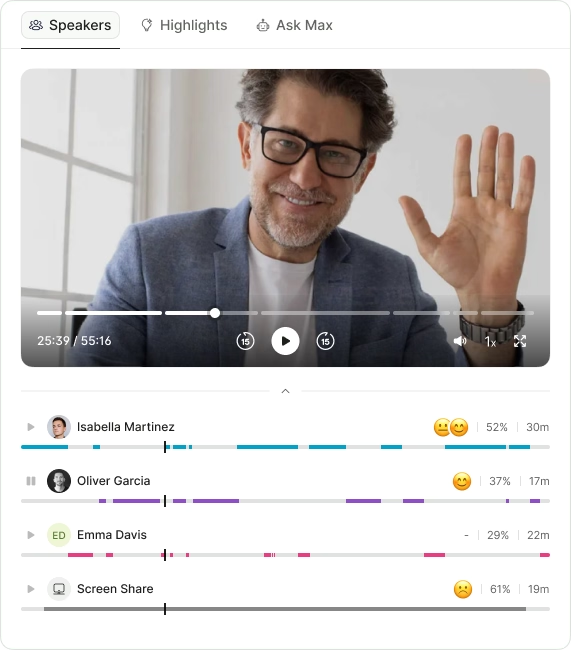
- Call summaries
- Sentiment analysis
- Next steps
- Search any call in seconds